PersistBench
Can 4D Foundation Models Remember?
Abstract.
Perceiving and remembering the visual world is fundamental to navigating and interacting with our environment. Current 4D foundation models can perceive and reconstruct dynamic environments, but how well they remember what they have perceived remains an open question. Existing benchmarks largely rely on pixel-level metrics and lack ground truth for objects once they leave the field of view.
We introduce PersistBench, a dataset and metric suite that uses 360° videos as omniscient ground truth to evaluate three object-centric aspects of visual memory: object permanence, motion continuity, and appearance preservation. Across 12 models from three model families, our evaluation reveals a substantial gap between synthesizing visible content and remembering objects beyond the input view.
Motivation.
Watch the people in these scenes as the camera turns away. Once they leave the view, can you still remember where they are, how they are moving, and what they look like?
Even without looking back, we retain a mental representation of the person: we expect them to continue to exist, anticipate how they move, and remember their appearance. This ability to reason about the world beyond immediate perception motivates our question:
Do 4D foundation models remember in a similar way as humans do?
What are 4D foundation models? In this work, we use the term for 4D vision models that reconstruct or generate dynamic 3D scenes, meaning three-dimensional environments evolving over time. They take visual observations and can be queried to render the scene from other viewpoints, allowing us to examine what they retain beyond the input view.
Examples include 4D reconstruction models such as 4DGT, which reconstruct a dynamic scene from input video; camera-controllable video generation models such as GEN3C, which synthesize views along a requested camera trajectory; and video-to-360° models such as Argus, which generate panoramic video from perspective inputs. We probe these models through their rendered outputs to ask whether they preserve the objects they have observed, including their motion and appearance.
Visual Memory.
An object should continue to exist, move coherently, and retain its identity, even when the camera looks away.
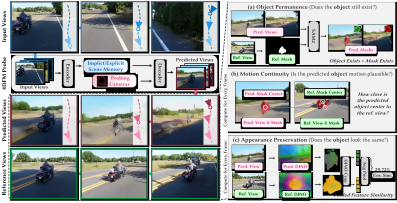
Our evaluation is inspired by developmental psychology. Research on core knowledge describes how humans represent objects beyond view and anticipate their motion (Spelke & Kinzler, 2007), while studies of object individuation distinguish tracking objects through space and time from recognizing them by appearance (Xu & Carey, 1996). Following these ideas, we evaluate three complementary aspects of visual memory.
Object permanence. Does the object still exist when we probe a view where it should be visible? We measure the fraction of frames with both a valid SAM2 track and VLM confirmation of the target object.
Motion continuity. Does the object’s location agree with its reference trajectory? We measure the distance between predicted and reference mask centers, normalized by object scale and mapped to a score with exponential decay.
Appearance preservation. Does the rendered object preserve the observed entity’s appearance? We compare mask-pooled DINOv2 features of the predicted and reference objects.
Using 360° Data.
How can we tell whether a model remembers correctly? We need a reference showing where the object is, how it moves, and what it looks like after it leaves the input view.
A conventional video cannot provide that reference: once the object leaves the frame, its state is no longer recorded. A plausible prediction alone does not tell us whether the model remembered the object it actually saw.
Our key idea is to use 360° video as omniscient ground truth. From the same recording, we crop two synchronized perspective videos. In the input, the camera turns away from the target. In the reference, the target remains visible, giving us its true state beyond the input field of view.
The model receives only the input video. We then query it with the reference camera trajectory and compare its predictions with the real reference, measuring object permanence, motion continuity, and appearance preservation separately for visible and invisible segments.
PersistBench contains 2,000 paired evaluation sequences: 1,000 with static objects and 1,000 with dynamic objects, spanning ten object categories. We curate these pairs from clips in 360-1M using camera pose estimation, object tracking, and constrained trajectory optimization, and evaluate 12 models across three families. While 2,000 pairs provide sufficient coverage for our evaluation, the same pipeline can scale to many more videos, supporting training data generation.
Leaderboard.
Every model with comparable visible and invisible outputs loses performance after the target leaves view. The three metrics reveal different strengths.
Static objects · 12 models · sorted by invisible-segment permanence
| Model | Memory | Permanence ↑ | Continuity ↑ | Appearance ↑ |
|---|---|---|---|---|
| Argus | Implicit | 84.06 (99.25) | 80.60 (95.86) | 68.49 (87.69) |
| GEN3C | Explicit | 83.97 (95.96) | 76.79 (86.98) | 82.61 (93.26) |
| TrajectoryCrafter | Explicit | 81.56 (99.55) | 70.14 (96.96) | 77.52 (96.30) |
| NeoVerse | Explicit | 78.92 (97.23) | 63.66 (85.84) | 80.42 (91.77) |
| CubeComposer | Implicit | 73.56 (98.94) | 75.51 (96.33) | 68.42 (93.18) |
| HyDRA | Implicit | 70.38 (N/A) | 38.90 (N/A) | 65.65 (N/A) |
| ReCamMaster | Implicit | 70.06 (95.48) | 51.73 (64.31) | 73.48 (89.36) |
| CogNVS | Explicit | 41.98 (99.29) | 67.91 (96.10) | 64.08 (92.65) |
| Imagine360 | Implicit | 34.17 (98.24) | 53.78 (93.93) | 40.78 (83.24) |
| ViewPoint | Implicit | 23.84 (77.29) | 46.14 (64.81) | 47.82 (74.28) |
| 4DGT | Explicit | 16.03 (97.00) | 70.34 (93.03) | 37.36 (83.69) |
| CUT3R | Implicit | 3.14 (66.43) | 70.66 (86.76) | 20.97 (56.71) |
Scores outside parentheses measure invisible segments; scores in parentheses measure visible segments. Underlined scores are the best in each column. All scores are percentages; higher is better. HyDRA’s visible scores are N/A because it only predicts after the target leaves view.
Visualizations.
Compare what each model predicts with what actually happens. Choose a scene, then play the videos or slide the time-aligned views across time. Turn on the object masks to see where memory succeeds or fails.
Gray bars show the selected metric at each frame: taller bars mean higher scores, from 0 to 100%. Pale bars indicate unavailable scores. The thin strip above marks the target as visible (blue), invisible (red), or partly visible (gray) in the input. The vertical line marks the current frame. Scores below the videos summarize the invisible segment.
Loading comparisons…
Takeaway.
Seeing is not remembering.
Every model with comparable visible and invisible outputs loses performance once the target leaves view. Strong reconstruction or novel-view synthesis does not imply persistent visual memory. The results suggest that current models still rely heavily on observed inputs rather than maintaining a lasting representation of the world.
Explicit conditioning helps visual memory. GEN3C, TrajectoryCrafter, and NeoVerse, which project input observations into target views before inpainting, generally retain objects more effectively. We hypothesize that this geometric guidance helps compensate for training data in which targets usually remain visible, turning generation into a more constrained refinement task.
Memory has multiple components. Models can preserve motion while losing the object or its identity. GEN3C and 4DGT both perform well on continuity, but GEN3C preserves object permanence much better. Likewise, NeoVerse and Imagine360 track dynamics similarly, while NeoVerse better preserves appearance. Permanence and appearance are strongly correlated (r = 0.93); continuity is less correlated with either (r = 0.34 and 0.54). One score cannot capture all three abilities.
Static memory predicts dynamic memory. Models generally remember static objects better, yet their static and dynamic scores are strongly correlated across all three metrics. This suggests shared underlying capabilities, so improving static memory may also benefit dynamic memory.
Carefully curated 360° data can improve visual memory. Panoramic training alone is not enough. Argus and CubeComposer perform well on static objects but drop substantially on dynamic ones. Argus, trained with more dynamic scenes and explicit camera noise, achieves the highest static permanence and continuity scores despite its older pretrained backbone. This suggests that dynamic content and diverse camera motion matter, making 360° data valuable for training as well as evaluation.
Together, these findings point to two directions: training data with frequent occlusion and reappearance, and architectures that combine explicit geometric conditioning with video generation. Whether the current architectural advantages persist under training designed specifically for memory remains an open question.
Additional findings and validation
Agreement with human judgments. Across the 12 methods, automatic and human rankings have Spearman correlations of 0.944 for permanence, 0.566 for continuity, and 0.986 for appearance. Agreement is strong for permanence and appearance and moderate for continuity. These values measure agreement between method rankings, not the accuracy of individual scores. Supplement D.3.
Longer sequences remain challenging. On ten additional dynamic sequences of about 60 seconds, 4DGT reaches 2.69% invisible permanence and 45.32% continuity, compared with 3.89% and 61.12% on the default subset. Its higher appearance score on the longer set comes from only three cases with valid tracked frames, so it does not demonstrate better appearance retention overall. Supplement E.1.
Object categories expose different strengths. Scores and model rankings vary by category. For example, GEN3C preserves appearance well across static and dynamic categories, while its continuity ranking varies. Several models track animals less accurately than dynamic decorations. Overall averages therefore hide useful differences. Supplement E.2.
Performance changes gradually within each segment. Scores generally decrease slightly over time without abrupt changes, and the broad trends remain similar despite some ranking changes. This supports reporting average scores alongside temporal views. Motion continuity stays relatively stable for some models and declines gradually for others, although alternative plausible motions become a greater concern over longer unseen intervals. Supplement E.3 and E.4.
The metric designs capture complementary failures. Tracking can detect a lost object that a semantic judge confuses with another instance; a semantic judge can reject an unrecognizable shape that tracking still follows. Combining both supports permanence evaluation. For appearance, averaging full-image DINOv2 features within the object mask best separates the high- and low-IoU groups in our ablation. Alternative continuity definitions largely preserve model rankings, while assigning zero to every untracked frame makes continuity more dependent on permanence. Supplement C.1 to C.4.
The main comparisons are robust to evaluation choices. Model rankings are largely preserved when replacing matching, tracking, judging, and appearance models. Camera perturbations affect continuity more than permanence or appearance, and rankings remain broadly consistent on sequences dominated by camera rotation. Camera handling is therefore a remaining influence, rather than a fully isolated factor. Supplement C.5 to C.7.
Visual memory differs from general video quality. On a 200-video subset, more than half of the rank correlations between our metrics and six WorldScore metrics are zero or negative. Object-centric memory evaluation therefore provides information beyond general consistency, dynamics, and visual quality. Supplement C.8.
Reference videos score close to 100%. Passing real reference videos through the same evaluation pipeline produces near-perfect scores. Small deviations reflect tracking and mask noise, establishing a useful baseline for interpreting model scores. Supplement C.9 and Table 4.
Scope and limitations
Camera-pose estimation, object matching, tracking, and scoring rely on pretrained models and can introduce errors. The scene distribution reflects the source YouTube 360° videos. Reference-based motion evaluation also has ambiguity: a plausible future need not exactly match the observed reference. See Section 7 and Supplement E.4.
Acknowledgements.
We thank Tao Tu and Xuyi Meng for sharing their data and research, and Qianxu Wang for being a total badass in the teaser. We also thank Noah Snavely, Bharath Hariharan, Yihong Sun, Kuan Wei Huang, Aditya Chetan, Rundong Luo, Haozheng Yu, and Lulu Zhao for valuable discussions and constructive feedback.
BibTeX
@misc{he2026persistbench,
  title  = {Can {4D} Foundation Models Remember?},
  author = {He, Guangzhao and Averbuch-Elor, Hadar and Ma, Wei-Chiu},
  year   = {2026},
  eprint = {2609.20819},
  archivePrefix = {arXiv},
  url    = {https://arxiv.org/abs/2609.20819}
}
References.
- Bai et al. ReCamMaster: Camera-Controlled Generative Rendering from a Single Video. ICCV, 2025.
- Chen, Khurana, and Ramanan. Reconstruct, Inpaint, Test-Time Finetune: Dynamic Novel-view Synthesis from Monocular Videos. NeurIPS, 2025.
- Chen et al. Out of Sight but Not Out of Mind: Hybrid Memory for Dynamic Video World Models. 2026.
- Duan et al. WorldScore: A Unified Evaluation Benchmark for World Generation. ICCV, 2025.
- Fang et al. ViewPoint: Panoramic Video Generation with Pretrained Diffusion Models. NeurIPS, 2025.
- Li et al. CubeComposer: Spatio-Temporal Autoregressive 4K 360° Video Generation from Perspective Video. CVPR, 2026.
- Luo et al. Beyond the Frame: Generating 360° Panoramic Videos from Perspective Videos. ICCV, 2025.
- Oquab et al. DINOv2: Learning Robust Visual Features without Supervision. TMLR, 2024.
- Ravi et al. SAM 2: Segment Anything in Images and Videos. ICLR, 2025.
- Ren et al. GEN3C: 3D-Informed World-Consistent Video Generation with Precise Camera Control. CVPR, 2025.
- Spelke and Kinzler. Core Knowledge. Developmental Science, 2007.
- Tan et al. Imagine360: Immersive 360 Video Generation from Perspective Anchor. NeurIPS, 2025.
- Wallingford et al. From an Image to a Scene: Learning to Imagine the World from a Million 360° Videos. NeurIPS, 2024.
- Wang et al. Continuous 3D Perception Model with Persistent State. CVPR, 2025.
- Xu and Carey. Infants’ Metaphysics: The Case of Numerical Identity. Cognitive Psychology, 1996.
- Xu et al. 4DGT: Learning a 4D Gaussian Transformer Using Real-World Monocular Videos. NeurIPS, 2025.
- Yang et al. NeoVerse: Enhancing 4D World Model with in-the-wild Monocular Videos. CVPR, 2026.
- Yu et al. TrajectoryCrafter: Redirecting Camera Trajectory for Monocular Videos via Diffusion Models. ICCV, 2025.